1 The puzzle
Causal selection is the process behind our intuition that an outcome happened because of a given event, or that one event is the cause of it. Judgments of actual causation decide which events count as causes at all; causal selection goes further and ranks them, singling out some as more important than others.
Example
When a forest catches fire after a lightning strike, people say the lightning caused the fire, not the oxygen in the air, although the oxygen was just as necessary. The rare event is preferred over the normal one.
Two patterns describe how the normality of a cause interacts with the structure of the causal rule:
- Abnormal inflation. When causes are jointly necessary (a conjunctive rule), the rarer cause receives more credit.
- Abnormal deflation. When each cause is sufficient on its own (a disjunctive rule), the pattern reverses and the more normal cause receives more credit.
Counterfactual simulation models explain both patterns by assuming that people imagine alternative scenarios, with normal scenarios coming to mind more easily, and then assess how each cause covaries with the outcome across those scenarios. Most of these models take a structural causal model as the representation people simulate over. The model below keeps the counterfactual idea but changes the representation: causal rules are represented as logic programs, compiled into neural networks whose hidden units mirror the clauses of the rule. That hidden structure, which a structural causal model does not have, turns out to matter for how people choose explanations, and above all for explanations that cite several causes at once.
Example
A weighted sum S := A + 2B + C can be computed by a network that connects every input directly to the output, or by one that routes signals through intermediate units. Both compute the same function but differ in internal structure. The claim of this notebook is that people represent causal rules through such non-minimal architectures, and that the hidden structure shapes the explanations they give.
2 The experiments
The model is tested on two experiments with games of chance (Figure 1). A player draws one ball from each of several urns; each urn holds 20 balls, some coloured and some white, so the proportion of coloured balls sets how likely each draw is to succeed. Participants saw the outcome of a round and rated how much each draw, or each combination of draws, was responsible for it.
Experiment 1 used the rule win when at least two of the three urns give a coloured ball, with probabilities 0.05, 0.5 and 0.95. It reuses the rule of Experiment 2a in Quillien and Lucas (2023). Plural causes (“urns A and B caused the win”) received ratings that could not be derived from the ratings of the single causes alone. The interface is shown in Appendix C (Figure 7).
Experiment 2 used a disjunctive rule, E \leftarrow A, B and E \leftarrow C, D: a win requires both urns of one team. Pairs on the same side of the disjunction (A, B or C, D) were preferred over pairs across it (A, C). When participants explained a loss, the effect of the rule’s structure disappeared, as if a negated plural were read homogeneously. Four rounds were shown (Table 1).
| Round | A | B | C | D |
|---|---|---|---|---|
| Overdetermined, win | yes | yes | yes | yes |
| Triple, win | yes | yes | no | yes |
| Overdetermined, loss | no | no | no | no |
| Triple, loss | no | no | yes | no |
3 The model in four steps
A causal rule enters the model as a logic program, a set of clauses each listing causes that are jointly sufficient for the effect. The model then works in four steps: it compiles the program into a network, samples counterfactual worlds over the network, adjusts the network’s weights to the samples, and scores each candidate cause by the relevance that reaches it. The code for every step is in Appendix A.
3.1From logic program to network
People are assumed to represent a Boolean causal rule as a set of Horn clauses, each a conjunction of conditions that suffices for the effect. The rule of Experiment 1 is three clauses:
E \leftarrow A, B \quad\; E \leftarrow A, C \quad\; E \leftarrow B, C
The program is compiled into a network by the CILP algorithm (Connectionist Inductive Learning and Logic Programming; d’Avila Garcez et al., 2002). The network has one input unit per variable, one hidden unit per clause, which behaves as a conjunctive gate, and one output unit per effect, which behaves as a disjunctive gate over the clauses. The hidden layer therefore mirrors the disjunctive normal form of the rule and keeps track of which variables are sufficient together. Every edge has weight \pm W, positive for a variable that appears as itself in a clause and negative for a negated one. Input units take as bias the log-odds of their prior, b_i = \operatorname{logit} p_i, so that rare events start out less active. With \mathrm{MAX}_P the largest of the clause lengths and of the numbers of clauses sharing a head, and \beta = 1 the slope of the activation function, the minimum activation and the weight are
\begin{gathered} A_{\min} = \frac{\mathrm{MAX}_P - 1}{\mathrm{MAX}_P + 1} + \frac{1}{\mathrm{MAX}_P}, \\[6pt] W = \frac{2}{\beta}\,\frac{\ln(1 + A_{\min}) - \ln(1 - A_{\min})}{\mathrm{MAX}_P\,(A_{\min} - 1) + A_{\min} + 1} \end{gathered} \tag{3.1}
# Experiment 1: the effect occurs when at least two of A, B, C occur
clauses <- list(
  list(head = "E", body = c("A", "B")),
  list(head = "E", body = c("A", "C")),
  list(head = "E", body = c("B", "C"))
)
# Prior probabilities of the causes: the low, middle and high urns
priors <- list(A = 0.05, B = 0.5, C = 0.95)

network <- generate_network_from_logic_program(clauses, priors)
round(unlist(network$biases), 2)
A B C Hab Hac Hbc E -2.94 0.00 2.94 -3.30 -3.30 -3.30 6.59
Figure 2 shows the compiled network in one counterfactual sample.
- True in this sample
- False
- Candidate cause
- Carries signal
3.2Sampling counterfactual worlds
Starting from the actual world, the model explores alternative worlds with Markov chain Monte Carlo sampling over the input units. Two samplers are implemented. The Metropolis–Hastings sampler (a mutation sampler) proposes to flip one input at a time and accepts the proposal with probability \min(1, e^{-\Delta L}), where L is a loss that combines the input biases with the hidden units’ agreement with their inputs. The Gibbs sampler resamples every input in turn from its conditional distribution. In both, hidden and output units are then updated deterministically.
Two forces shape the samples. The biases make normal events more frequent, pulling the chain away from an abnormal actual world. The hidden units resist transitions that would flip them, which anchors the chain near the actual world and groups variables by the clauses they share. Which force wins depends on the rule and the priors. For the rule of Experiment 1 (Figure 3) the pull of the priors dominates: the rare A is switched off almost at once, and the chains then spend nearly all their time in the two states where A is absent and C present, with B on or off. The Boys & Girls example in Appendix B shows the opposite case, where the Metropolis–Hastings chains spend 42% of their time in the actual world.
- Outcome occurs
- Outcome does not occur
- Actual world
3.3Learning from the samples
As the model visits counterfactual worlds, it updates its weights by layer-wise feedback propagation (LFP), a procedure adapted from layer-wise relevance propagation (LRP) in interpretable machine learning. In each sampled world the outcome unit receives a reward that depends on the actual outcome: when the effect occurred, the reward is the product of the outcome’s activations in the actual world and in the sample, positive when the sample agrees; when it did not occur, the reward is the size of the sample’s activation,
r_{E}^{i} = \begin{cases} a_{E}^{\mathrm{AW}}\, a_{E}^{i} & \text{if } a_{E}^{\mathrm{AW}} > 0 \\ \lvert a_{E}^{i} \rvert & \text{if } a_{E}^{\mathrm{AW}} < 0 \end{cases} \tag{3.2}
where a_{E}^{\mathrm{AW}} is the outcome’s activation in the actual world and a_{E}^{i} its activation in sample i. The reward then flows backwards, and each weight changes in proportion to its share of the unit’s net input,
\delta w_{ij} = \eta\, \frac{\lvert w_{ij} \rvert\, a_i}{\lvert z_j^{+} \rvert + \lvert z_j^{-} \rvert + \varepsilon}\, \operatorname{sign}(z_j)\, r_j \tag{3.3}
with learning rate \eta. Biases are updated in the same way, as a connection from a unit that is always on. Connections from inputs that covary with the outcome are strengthened, so the covariation between causes and outcome ends up encoded in the weights. Updates can be applied in two ways. The Cumulative variant averages them over all samples and applies them once sampling is over; the AsWeGo variant applies them after every sample, so later samples are drawn from the already updated network.
R code for Tables 2 and 3
set.seed(11)
init <- generate_initial_hidden_states(list(A = 1, B = 1, C = 1, E = 1),
                                       network$network)
learned <- run_simulation(network, init, init, num_simulations = 500, n_samples = 20,
weight_update_timing = "Cumulative", learning_rate = 1.15)| Edge | Before | After | Change |
|---|---|---|---|
| A → H_1 | 3.60 | 3.75 | +0.15 |
| A → H_2 | 3.60 | 3.76 | +0.16 |
| B → H_1 | 3.60 | 3.61 | +0.01 |
| B → H_3 | 3.60 | 3.76 | +0.16 |
| C → H_2 | 3.60 | 3.49 | −0.11 |
| C → H_3 | 3.60 | 3.63 | +0.03 |
| H_1 → E | 3.60 | 3.23 | −0.37 |
| H_2 → E | 3.60 | 3.25 | −0.35 |
| H_3 → E | 3.60 | 3.66 | +0.06 |
3.4Scoring causes
Once learning is over, relevance is propagated from the outcome back through the updated network in the actual world (alpha-beta LRP, positive paths only for a positive outcome). Each input unit c receives a relevance R_c. A cause set C, single or plural, is then scored by its relevance divided by the path complexity of the routes it uses:
\begin{aligned} \kappa(C, E) &= \frac{\sum_{c \in C} R_c}{\mathcal{C}(C, E)}, \quad \text{with} \\[6pt] \mathcal{C}(C, E) &= \#_{\mathrm{ED}}(C, E) + \lvert \mathrm{Idle}(C, E) \rvert \end{aligned} \tag{3.4}
Definition
\#_{\mathrm{ED}}(C, E) is the largest number of positive activation paths from C to the outcome that share no edge, so a set that recruits two clauses needs two routes. \mathrm{Idle}(C, E) is the set of causes in C that lie on no positive path at all; each one adds to the denominator without adding relevance. The measure therefore rewards explanations whose contribution travels through a single mechanism, and penalises plural causes that borrow from separate clauses. This is the definition of chapter 4 (equation path-complexity), with both terms weighted equally.
For a negative outcome the derivation of \neg E goes through the failure to derive E, so every path to the outcome shares the final edge \neg E \leftarrow {\sim}E. Path complexity then reduces to one route for every cause set, plus one for each cause in the set whose state pushed towards the effect that did not happen (a present cause with positive weights, or an absent one with negative weights). Table 3 gives the scores for the network of Table 2.
| Cause set | Relevance \sum R_c | Complexity \mathcal{C} | \kappa |
|---|---|---|---|
| A, B, C | 1.000 | 3 | .333 |
| B, C | .671 | 3 | .224 |
| A, B | .668 | 3 | .223 |
| A, C | .660 | 3 | .220 |
| B | .340 | 2 | .170 |
| C | .332 | 2 | .166 |
| A | .329 | 2 | .164 |
4 What the model predicts
The two classic patterns can be tested on the smallest programs that show them, a conjunctive rule E \leftarrow A, B and a disjunctive rule E \leftarrow A; E \leftarrow B, with both causes present and the outcome occurring. Figure 4 sets the model’s importance for A next to the ratings that Morris et al. (2019) collected in the same design.
- P(A) = 0.1
- P(A) = 0.5
- P(A) = 0.9
- Other levels of P(A)
Key result
The model reproduces both abnormal inflation and abnormal deflation without any term that refers to normality directly. The patterns come from where the samples go and from what the network learns from them.
5 Parameters
Besides \gamma, which only maps importance onto the rating scale (Section 6.1), the model has two free parameters for a given rule: the number of samples per chain n and the learning rate \eta. Figure 5 shows how the importance of the rare cause A, with P(A) = 0.1 and P(B) = 0.9, changes with both, under the two update timings.
- \eta = 0.1
- \eta = 0.25
- \eta = 0.5
- \eta = 0.75
- \eta = 1
Under the Cumulative timing, the score of A is nearly flat in n for any given \eta: updates are applied once, at the end, and more samples mainly make them less anchored to the actual world, which matters little for these simple patterns. The effect of \eta is stable and monotonic; a larger learning rate magnifies whichever pattern emerges.
Under AsWeGo, contrasts are larger and sometimes non-linear. Each sample changes the weights before the next one is drawn, so early updates that favour a cause make later samples favour it too. Pushed far enough, this feedback changes the rule itself: in the conjunctive program the first samples, all drawn near (A{=}1, B{=}1), strengthen both connections to the shared clause unit and shrink its negative bias, until the gate behaves almost disjunctively and the score of the rare A drops.
Because of this runaway effect the number of samples is fixed at n = 20 for the fit, and only \eta is fitted. A small fixed n keeps the parameter space small, keeps sampling anchored to the actual world (which gives the model an account of anchoring), stays within the chain lengths of other sampling models of causal judgment (e.g. Davis and Rehder, 2020), and is cognitively plausible: people consider a handful of nearby alternatives, not an exhaustive set. The Cumulative predictions are robust to the exact value chosen.
6 Fit to Experiment 2
6.1From importance to ratings
The model gives every cause set an importance \kappa between 0 and 1. Participants’ ratings may follow a different absolute scale while preserving the differences between cause sets, so predictions are compared with \kappa^{\gamma}, and \eta and \gamma are fitted together by grid search, maximising the correlation between predictions and mean ratings across the four rounds (Appendix D). The dissertation’s values, used throughout this page, are \eta = 1.15 and \gamma = 0.58 for the Cumulative variant and \eta = 0.13 and \gamma = 0.56 for AsWeGo, both with n = 20 samples per chain and 500 chains. Rerunning the simulations and the grid search puts the best cells at \eta = 1.10, \gamma = 0.58 and \eta = 0.15, \gamma = 0.56, with correlations that differ from those at the published values by less than .001: the optimum is flat, and the published values are kept.
6.2Predictions against ratings
Figure 6 compares the Cumulative model with the mean ratings, round by round, and Table 4 summarises the agreement of both variants.
R code for Figure 6
model <- read.csv("_data/comparison_df_cumulative_extracted.csv")   # published predictions, kappa^gamma
fit <- exp2_summary(exp2_ratings()) |>
  merge(model, by.x = c("scenario", "cause_set"), by.y = c("scenario_name", "cause_set")) |>
  transform(panel = scen_labels[scenario], label = cause_set,
            group = lengths(strsplit(cause_set, ",")),
            model = 1 + 8 * model_pred)          # on the 1-9 rating scale
r_by <- sapply(split(fit, fit$panel), function(d) cor(d$mean, d$model))- Participants, mean and 95% interval
- Model, Cumulative variant
Show the data as a table
| Round | Cause set | Mean | 95% CI | Model |
|---|---|---|---|---|
| Overdetermined, win | A | 4.91 | 4.63–5.20 | 4.33 |
| Overdetermined, win | B | 5.31 | 5.00–5.61 | 4.52 |
| Overdetermined, win | C | 5.20 | 4.90–5.49 | 4.81 |
| Overdetermined, win | D | 4.83 | 4.54–5.11 | 4.65 |
| Overdetermined, win | A, B | 8.02 | 7.83–8.22 | 6.12 |
| Overdetermined, win | A, C | 4.68 | 4.38–4.97 | 4.58 |
| Overdetermined, win | B, C | 5.12 | 4.81–5.43 | 4.67 |
| Overdetermined, win | C, D | 8.01 | 7.82–8.20 | 6.58 |
| Overdetermined, win | A, B, C | 7.01 | 6.77–7.26 | 5.50 |
| Overdetermined, win | A, B, D | 7.01 | 6.78–7.25 | 5.43 |
| Triple, win | A | 5.40 | 5.11–5.69 | 6.21 |
| Triple, win | B | 5.95 | 5.64–6.26 | 6.49 |
| Triple, win | D | 2.50 | 2.26–2.75 | 1.00 |
| Triple, win | A, B | 8.55 | 8.40–8.69 | 9.00 |
| Triple, win | A, D | 3.88 | 3.59–4.17 | 4.48 |
| Triple, win | B, D | 4.02 | 3.73–4.30 | 4.67 |
| Triple, win | A, B, D | 6.69 | 6.42–6.96 | 6.35 |
| Overdetermined, loss | A | 5.05 | 4.75–5.36 | 4.60 |
| Overdetermined, loss | B | 4.29 | 3.99–4.59 | 4.46 |
| Overdetermined, loss | C | 4.56 | 4.26–4.86 | 4.53 |
| Overdetermined, loss | D | 5.12 | 4.80–5.43 | 4.73 |
| Overdetermined, loss | A, B | 6.28 | 6.00–6.56 | 6.27 |
| Overdetermined, loss | A, C | 6.25 | 5.96–6.53 | 6.32 |
| Overdetermined, loss | A, D | 6.66 | 6.38–6.94 | 6.48 |
| Overdetermined, loss | B, C | 5.84 | 5.53–6.15 | 6.22 |
| Overdetermined, loss | B, D | 6.00 | 5.71–6.29 | 6.38 |
| Overdetermined, loss | C, D | 6.46 | 6.19–6.73 | 6.43 |
| Overdetermined, loss | A, C, D | 7.63 | 7.42–7.83 | 7.85 |
| Overdetermined, loss | B, C, D | 7.37 | 7.14–7.60 | 7.76 |
| Triple, loss | A | 4.40 | 4.11–4.70 | 4.50 |
| Triple, loss | B | 3.78 | 3.49–4.06 | 4.42 |
| Triple, loss | D | 6.13 | 5.81–6.44 | 6.53 |
| Triple, loss | A, B | 5.68 | 5.38–5.97 | 6.17 |
| Triple, loss | A, D | 6.67 | 6.38–6.95 | 7.87 |
| Triple, loss | B, D | 6.19 | 5.90–6.48 | 7.82 |
| Triple, loss | A, B, D | 7.61 | 7.40–7.83 | 9.00 |
| Variant | \eta | \gamma | r | RMSE | AIC | BIC |
|---|---|---|---|---|---|---|
| Cumulative | 1.15 | 0.58 | .849 | 0.82 | 6,652 | 6,667 |
| AsWeGo | 0.13 | 0.56 | .851 | 0.82 | 6,624 | 6,639 |
7 Why the model predicts what it does
Overdetermined win. All four urns gave a coloured ball. Among single causes, the rarer member of each team tends to receive more credit than its partner, a form of abnormal inflation within each side of the disjunction. Cross-team pairs such as A, C or B, C are rated below the same-team pairs A, B and C, D: they draw their relevance through two different clause units, so their path complexity is two. Triples sit in between, more complex than the same-team pairs but no more complex than the cross-team pairs they contain, which matches where participants put them.
Triple win. Three urns gave a coloured ball and the round was still won. The urn whose ball did not help is essentially irrelevant to the win and receives a near-zero score. The model does not exclude it by a separate filter; little relevance happens to reach an unused path. Adding it to any cause set lowers the set’s score, because it adds complexity without adding relevance.
Losses. For a lost round the outcome is derived from the failure to derive a win, which changes two things. Credit flips sign, so the events that did not help the win get the credit, and the complexity penalty disappears, because failing to derive E means trying every route anyway. In the overdetermined loss the model therefore reverses the pattern of the win and favours A and D, and it follows a “the more variables, the better” trend for plural causes, both as participants do. In the triple loss, A, B can be rated above either A or B alone, although either one suffices to explain the loss, and D receives a high score because it alone made the C, D route inactive and inherits all the relevance flowing through it.
A Implementation
This appendix shows the model code, which lives in models/_R/model/ and is used unchanged by the notebook, the computation scripts and the parity tests of the interactive demo.
A.1Program to network (CILP)
generate_network_from_logic_program()
generate_network_from_logic_program <- function(clauses, input_probabilities, plot_network = FALSE) {

  # =====================================================================
  # Nested function: parse_clauses()
  # Gathers heads, bodies, negative literal counts, etc.
  # =====================================================================
  parse_clauses <- function(clauses) {
    all_literals        <- c()
    heads               <- c()
    body_literals_list  <- list()
    n_l_list            <- c()
    k_l_list            <- c()
    mu_l_list           <- c()

    # Collect head names without '!'
    head_names <- sapply(clauses, function(clause) gsub("!", "", clause$head))
    # Count how many clauses share each head
    head_counts <- table(head_names)

    for (i in seq_along(clauses)) {
      clause <- clauses[[i]]
      head   <- clause$head
      body   <- clause$body
      heads  <- c(heads, head)

      # --------------------------------------------------------
      # Record each literal (removing '!')
      # --------------------------------------------------------
      literals   <- gsub("!", "", body)
      head_name  <- gsub("!", "", head)
      all_literals <- c(all_literals, literals, head_name)

      # --------------------------------------------------------
      # Negative literal count & total literal count
      # --------------------------------------------------------
      n_l       <- sum(grepl("^!", body))
      n_l_list  <- c(n_l_list, n_l)
      k_l       <- length(body)
      k_l_list  <- c(k_l_list, k_l)

      # --------------------------------------------------------
      # Store the body in a list
      # --------------------------------------------------------
      body_literals_list[[i]] <- body

      # --------------------------------------------------------
      # mu_l = # of clauses sharing the same head
      # --------------------------------------------------------
      mu_l <- as.numeric(head_counts[head_name])
      mu_l_list <- c(mu_l_list, mu_l)
    }

    # Remove duplicates for all_literals
    all_literals <- unique(all_literals)

    return(list(
      all_literals       = all_literals,
      heads              = heads,
      body_literals_list = body_literals_list,
      n_l_list           = n_l_list,
      k_l_list           = k_l_list,
      mu_l_list          = mu_l_list
    ))
  }

  # =====================================================================
  # Nested function: compute_parameters()
  # Computes thresholds for A_min and W based on the maximum body size
  # and #clauses per head. Reflects Equations from CILP approach.
  # =====================================================================
  compute_parameters <- function(parsed_clauses, D = 1, beta = 1) {
    k_l_list  <- parsed_clauses$k_l_list
    mu_l_list <- parsed_clauses$mu_l_list

    # --------------------------------------------------------
    # MAX_P is the largest of (max #body-literals, max #clauses sharing the same head)
    # --------------------------------------------------------
    MAX_P <- max(c(k_l_list, mu_l_list))

    # --------------------------------------------------------
    # A_min slightly above (MAX_P - 1)/(MAX_P + 1)
    # --------------------------------------------------------
    A_min_threshold <- (MAX_P - 1) / (MAX_P + 1)
    A_min           <- A_min_threshold + 1 / MAX_P

    # --------------------------------------------------------
    # Weight magnitude W from eqn in thesis
    # --------------------------------------------------------
    numerator   <- log(1 + A_min) - log(1 - A_min)
    denominator <- MAX_P * (A_min - 1) + A_min + 1
    W           <- (2 / beta) * (numerator / denominator)
    W           <- W / D

    # --------------------------------------------------------
    # Theta (hidden thresholds): ensures a conjunctive gate approximation
    # --------------------------------------------------------
    theta_l_list <- ((1 + A_min) * (k_l_list - 1) / 2) * W

    # --------------------------------------------------------
    # Theta (output thresholds): ensures a disjunctive gate approximation
    # --------------------------------------------------------
    output_neurons <- unique(gsub("!", "", parsed_clauses$heads))
    mu_A_list      <- sapply(output_neurons, function(output_neuron) {
      sum(gsub("!", "", parsed_clauses$heads) == output_neuron)
    })

    theta_A_list <- ((1 + A_min) * (1 - mu_A_list) / 2) * W
    names(theta_A_list) <- output_neurons

    return(list(
      A_min         = A_min / D,
      W             = W,
      theta_l_list  = theta_l_list,
      theta_A_list  = theta_A_list
    ))
  }

  # =====================================================================
  # Nested function: create_network()
  # Builds a network object with:
  #   - W_input_hidden
  #   - W_hidden_output
  #   - bias_input, bias_hidden, bias_output
  # For subsequent translation into the final "sampling format."
  # =====================================================================
  create_network <- function(parsed_clauses, params, input_probabilities) {
    all_literals       <- parsed_clauses$all_literals
    body_literals_list <- parsed_clauses$body_literals_list
    heads              <- parsed_clauses$heads
    n_clauses          <- length(heads)

    # --------------------------------------------------------
    # Identify input vs. hidden vs. output neurons
    # --------------------------------------------------------
    input_neurons <- unique(unlist(body_literals_list))
    input_neurons <- gsub("!", "", input_neurons)
    input_neurons <- unique(input_neurons)

    hidden_neurons <- sapply(seq_len(n_clauses), function(i) {
  clause_body <- body_literals_list[[i]]            # e.g. c("A", "B") or c("!A", "B")
  clause_body_clean <- gsub("!", "", clause_body)   # remove any "!"
  clause_body_lower <- tolower(clause_body_clean)   # turn A->a, B->b, etc.

  # Collapse the body-literal names into one string, e.g. "ab"
  subscript <- paste0(clause_body_lower, collapse = "")

  # Construct a label like "H_ab"
  hidden_name <- paste0("H", subscript)
  return(hidden_name)
})

    output_neurons <- unique(gsub("!", "", heads))

    # Index mappings (not strictly needed, but helps clarity)
    input_indices  <- setNames(seq_along(input_neurons),   input_neurons)
    hidden_indices <- setNames(seq_along(hidden_neurons),  hidden_neurons)
    output_indices <- setNames(seq_along(output_neurons),  output_neurons)

    # --------------------------------------------------------
    # Initialize empty weight matrices & biases
    # --------------------------------------------------------
    W_input_hidden  <- matrix(0, nrow = length(input_neurons),  ncol = n_clauses)
    W_hidden_output <- matrix(0, nrow = n_clauses,              ncol = length(output_neurons))

    bias_hidden     <- params$theta_l_list * (-1)
    names(bias_hidden) <- hidden_neurons

    bias_output     <- -1 * params$theta_A_list[output_neurons]
    names(bias_output) <- output_neurons

    W <- params$W

    # --------------------------------------------------------
    # Fill W_input_hidden with ±W (sign depends on negation)
    # --------------------------------------------------------
    for (i in seq_len(n_clauses)) {
      clause_body <- body_literals_list[[i]]
      for (literal in clause_body) {
        is_negative  <- startsWith(literal, "!")
        literal_name <- gsub("!", "", literal)
        input_idx    <- input_indices[[literal_name]]

        weight <- ifelse(is_negative, -W, W)
        W_input_hidden[input_idx, i] <- weight
      }
    }

    # --------------------------------------------------------
    # Fill W_hidden_output: also ±W depending on negation in heads
    # --------------------------------------------------------
    for (i in seq_len(n_clauses)) {
      head        <- heads[[i]]
      is_negative <- startsWith(head, "!")
      head_name   <- gsub("!", "", head)
      output_idx  <- output_indices[[head_name]]

      weight <- ifelse(is_negative, -W, W)
      W_hidden_output[i, output_idx] <- weight
    }

    # --------------------------------------------------------
    # Compute biases for input neurons from input_probabilities
    # --------------------------------------------------------
    bias_input <- numeric(length(input_neurons))
    names(bias_input) <- input_neurons
    for (input_neuron in input_neurons) {
      p <- input_probabilities[[input_neuron]]
      b <- log(p / (1 - p))  # logistic transform to get bias
      bias_input[input_neuron] <- b
    }

    # Label the rows & cols for clarity
    rownames(W_input_hidden) <- input_neurons
    colnames(W_input_hidden) <- hidden_neurons
    rownames(W_hidden_output) <- hidden_neurons
    colnames(W_hidden_output) <- output_neurons

    return(list(
      W_input_hidden  = W_input_hidden,
      W_hidden_output = W_hidden_output,
      bias_input      = bias_input,
      bias_hidden     = bias_hidden,
      bias_output     = bias_output,
      input_neurons   = input_neurons,
      hidden_neurons  = hidden_neurons,
      output_neurons  = output_neurons
    ))
  }

  # =====================================================================
  # Nested function: convert_network_to_sampling_format()
  # Turns the above raw network into a list of edges, biases, layers, etc.
  # for easy sampling or forward passes.
  # =====================================================================
  convert_network_to_sampling_format <- function(network) {
    nodes <- c(network$input_neurons, network$hidden_neurons, network$output_neurons)

    # --------------------------------------------------------
    # Build a named list of biases (input, hidden, output)
    # --------------------------------------------------------
    biases <- list()
    for (input_neuron in network$input_neurons) {
      biases[[input_neuron]] <- network$bias_input[[input_neuron]]
    }
    for (hidden_neuron in network$hidden_neurons) {
      biases[[hidden_neuron]] <- network$bias_hidden[[hidden_neuron]]
    }
    for (output_neuron in network$output_neurons) {
      biases[[output_neuron]] <- network$bias_output[[output_neuron]]
    }

    # --------------------------------------------------------
    # Build edges (from input->hidden, hidden->output)
    # --------------------------------------------------------
    edges <- list()

    W_input_hidden  <- network$W_input_hidden
    input_neurons   <- network$input_neurons
    hidden_neurons  <- network$hidden_neurons

    for (i in seq_along(input_neurons)) {
      for (j in seq_along(hidden_neurons)) {
        weight <- W_input_hidden[i, j]
        if (weight != 0) {
          edges[[length(edges) + 1]] <- list(
            from   = input_neurons[i],
            to     = hidden_neurons[j],
            weight = weight
          )
        }
      }
    }

    W_hidden_output <- network$W_hidden_output
    output_neurons  <- network$output_neurons

    for (i in seq_along(hidden_neurons)) {
      for (j in seq_along(output_neurons)) {
        weight <- W_hidden_output[i, j]
        if (weight != 0) {
          edges[[length(edges) + 1]] <- list(
            from   = hidden_neurons[i],
            to     = output_neurons[j],
            weight = weight
          )
        }
      }
    }

    # --------------------------------------------------------
    # Define layer structure
    # --------------------------------------------------------
    layers <- list(
      network$input_neurons,
      network$hidden_neurons,
      network$output_neurons
    )

    return(list(
      nodes   = nodes,
      biases  = biases,
      edges   = edges,
      layers  = layers,
      network = network  # Original network object for reference
    ))
  }

  # =====================================================================
  # Nested function: create_causal_graph()
  # Optionally plots the generated network as a diagram, using DiagrammeR.
  # =====================================================================
  create_causal_graph <- function(network) {
    library(DiagrammeR)

    graph       <- DiagrammeR::create_graph()
    nodes       <- list()
    node_labels <- list()

    # 1) Input nodes
    for (input in network$input_neurons) {
      bias <- round(network$bias_input[input], 2)
      input_label <- paste0(input, "\nBias: ", bias)
      graph <- graph %>%
        add_node(
          label   = input_label,
          type    = "input",
          node_aes= node_aes(shape = "circle", color = "lightblue")
        )
      nodes             <- c(nodes, input)
      node_labels[[input]] <- input_label
    }

    # 2) Hidden nodes
    for (i in seq_along(network$hidden_neurons)) {
      hidden_node  <- network$hidden_neurons[i]
      bias         <- round(network$bias_hidden[i], 2)
      hidden_label <- paste0(hidden_node, "\nBias: ", bias)
      graph <- graph %>%
        add_node(
          label   = hidden_label,
          type    = "hidden",
          node_aes= node_aes(shape = "circle", color = "orange")
        )
      nodes             <- c(nodes, hidden_node)
      node_labels[[hidden_node]] <- hidden_label
    }

    # 3) Output nodes
    for (i in seq_along(network$output_neurons)) {
      output_node  <- network$output_neurons[i]
      bias         <- round(network$bias_output[i], 2)
      output_label <- paste0(output_node, "\nBias: ", bias)
      graph <- graph %>%
        add_node(
          label   = output_label,
          type    = "output",
          node_aes= node_aes(shape = "circle", color = "lightgreen")
        )
      nodes                <- c(nodes, output_node)
      node_labels[[output_node]] <- output_label
    }

    # 4) Edges: input->hidden
    for (i in seq_along(network$input_neurons)) {
      input_node <- network$input_neurons[i]
      for (j in seq_along(network$hidden_neurons)) {
        hidden_node <- network$hidden_neurons[j]
        weight      <- network$W_input_hidden[i, j]
        if (weight != 0) {
          edge_color <- ifelse(weight > 0, "green", "red")
          graph <- graph %>% add_edge(
            from    = node_labels[[input_node]],
            to      = node_labels[[hidden_node]],
            rel     = "causal",
            edge_aes= edge_aes(label = paste("W:", round(weight, 2)), color = edge_color)
          )
        }
      }
    }

    # 5) Edges: hidden->output
    for (i in seq_along(network$hidden_neurons)) {
      hidden_node <- network$hidden_neurons[i]
      for (j in seq_along(network$output_neurons)) {
        output_node <- network$output_neurons[j]
        weight      <- network$W_hidden_output[i, j]
        if (weight != 0) {
          edge_color <- ifelse(weight > 0, "green", "red")
          graph <- graph %>% add_edge(
            from    = node_labels[[hidden_node]],
            to      = node_labels[[output_node]],
            rel     = "causal",
            edge_aes= edge_aes(label = paste("W:", round(weight, 2)), color = edge_color)
          )
        }
      }
    }

    # Return the rendered graph (will display in knitr chunks when called)
    render_graph(graph, layout = "tree")
  }

  # =====================================================================
  # Main body of generate_network_from_logic_program()
  # Orchestrates all nested steps, returning sampling_network.
  # =====================================================================

  # 1) Parse the user-provided clauses
  parsed_clauses <- parse_clauses(clauses)

  # 2) Compute parameters (A_min, W, thresholds)
  params <- compute_parameters(parsed_clauses)

  # 3) Create raw network object
  network <- create_network(parsed_clauses, params, input_probabilities)

  # 4) Convert it to sampling format (edges, layers, biases)
  sampling_network <- convert_network_to_sampling_format(network)

  # 5) Create graph if requested
  network_graph <- NULL
  if (plot_network) {
    network_graph <- create_causal_graph(network)
  }

  # 6) Return the final "sampling_network" object (with optional graph)
  sampling_network$graph <- network_graph
  return(sampling_network)
}A.2Samplers
mh_layered_sampler() and layer_gibbs_sampler()
# ===============================================================
# generate_initial_hidden_states():
#   Initializes the state of hidden neurons given input states
#   using simple sign checks on net inputs (bias + weighted sum).
# ===============================================================
generate_initial_hidden_states <- function(initial_state_io, network) {
  input_neurons    <- network$input_neurons
  hidden_neurons   <- network$hidden_neurons
  W_input_hidden   <- network$W_input_hidden
  bias_hidden      <- network$bias_hidden

  # Initialize the full state with whatever inputs/outputs were provided
  initial_state <- initial_state_io

  # For each hidden neuron, compute the net input from input neurons
  # and assign state = +1 if net_input>0, else -1.
  for (hidden_neuron in hidden_neurons) {
    net_input <- bias_hidden[[hidden_neuron]]

    # Sum over all input neurons
    for (input_neuron in input_neurons) {
      weight <- W_input_hidden[input_neuron, hidden_neuron]
      if (!is.null(initial_state[[input_neuron]])) {
        net_input <- net_input + weight * initial_state[[input_neuron]]
      } else {
        # If no explicit value, assume -1
        net_input <- net_input + weight * (-1)
      }
    }

    # Threshold at 0
    state_value <- ifelse(net_input > 0, 1, -1)
    initial_state[[hidden_neuron]] <- state_value
  }

  return(initial_state)
}

# ===============================================================
# Simple sigmoid function for computing probabilities from net inputs
# ===============================================================
sigmoid <- function(x) {
  classent <- class(x)
  if (!(classent == "numeric")) {
  cat("sigmoid() input x =", x, " class=", class(x), "\n")
  }
  1 / (1 + exp(-x))
}

# ===============================================================
# Negative log-likelihood loss, comparing {+1/-1} target to a predicted probability
# ===============================================================
compute_loss_NLL <- function(target, prob) {
  if (target == 1) {
    -log(prob)
  } else if (target == -1) {
    -log(1 - prob)
  } else {
    stop("Target must be 1 or -1")
  }
}

# ===============================================================
# mh_layered_sampler():
#   Implements a layered Metropolis-Hastings approach.
#   - Randomly flips one input node at a time, then computes acceptance prob
#   - Deterministic updates for hidden/output layers
# ===============================================================
mh_layered_sampler <- function(
  iterations, nodes, layers, edges, biases, initial_state = NULL, temperature = 1
) {
  # Identify which nodes are input nodes (first layer)
  input_nodes <- layers[[1]]

  # Scale biases by temperature
  biases_T <- list()
  for (node in nodes) {
    biases_T[[node]] <- biases[[node]] / temperature
  }

  # Scale weights by temperature
  edges_T <- lapply(edges, function(e) list(
    from   = e$from,
    to     = e$to,
    weight = e$weight / temperature
  ))

  # Initialize state: either all +1 or a user-supplied initial_state
  if (is.null(initial_state)) {
    state <- setNames(rep(1, length(nodes)), nodes)
  } else {
    # Ensure it's a named list
    if (!is.list(initial_state)) {
      state <- as.list(initial_state)
    } else {
      state <- initial_state
    }
  }

  # Prepare a data.frame to store the sequence of sampled states
  states <- data.frame(matrix(ncol = length(nodes), nrow = iterations + 1))
  colnames(states) <- nodes

  # Record the initial state in the first row
  states[1, ] <- sapply(nodes, function(n) state[[n]])

  # Build a "parent map" for quick reference: which nodes feed into each node?
  parent_map <- list()
  for (node in nodes) {
    parent_map[[node]] <- c()
  }
  for (e in edges_T) {
    parent_map[[e$to]] <- c(parent_map[[e$to]], e$from)
  }

  # Also build an edge_map from "X->Y" to the scaled weight
  edge_map <- list()
  for (e in edges_T) {
    key <- paste(e$from, e$to, sep = "->")
    edge_map[[key]] <- e$weight
  }

  # ===============================================================
  # MAIN SAMPLING LOOP
  # ===============================================================
  for (iter in 1:iterations) {
    # -------------------------------------------
    # 1) Metropolis-Hastings step for input layer
    # -------------------------------------------
    current_input_state <- unlist(state[input_nodes])

    # Randomly select one input node to flip
    node_to_flip <- sample(input_nodes, 1)

    # Proposed state: flip that node
    proposed_state <- state
    proposed_state[[node_to_flip]] <- -proposed_state[[node_to_flip]]

    # We'll define an internal function to compute total loss for
    # the input nodes + their immediate children
    compute_total_loss <- function(state_snapshot) {
      total_loss <- 0

      # For each input node, compute negative log-likelihood based on its bias
      for (inp in input_nodes) {
        net_input_inp <- biases_T[[inp]]
        prob_inp       <- sigmoid(net_input_inp)
        total_loss     <- total_loss + compute_loss_NLL(state_snapshot[[inp]], prob_inp)

        # Now consider children: each child is a hidden node that depends on "inp"
        children_edges <- edges_T[sapply(edges_T, function(e) e$from == inp)]
        for (child_edge in children_edges) {
          child <- child_edge$to
          net_input_child <- biases_T[[child]]
          parents         <- parent_map[[child]]

          # Sum up parent's contributions
          for (parent in parents) {
            edge_key       <- paste(parent, child, sep = "->")
            net_input_child <- net_input_child + edge_map[[edge_key]] * state_snapshot[[parent]]
          }

          # Evaluate child's predicted probability
          prob_child <- sigmoid(net_input_child)

          # The child's observed state is +1 or -1, so compute NLL
          # We scale or adjust the child's loss by length(children_edges) and weight magnitude, to reduce extremes
          this_loss_child <- compute_loss_NLL(state_snapshot[[child]], prob_child) /
            length(children_edges) / abs(edge_map[[edge_key]])

          total_loss <- total_loss + this_loss_child
        }
      }
      return(total_loss)
    }

    # Compute loss for current vs. proposed states
    loss_current  <- compute_total_loss(state)
    loss_proposed <- compute_total_loss(proposed_state)

    # Metropolis-Hastings acceptance probability
    delta_loss       <- loss_proposed - loss_current
    acceptance_prob  <- min(1, exp(-delta_loss))

    # Decide whether to accept
    if (runif(1) < acceptance_prob) {
      # Accept the proposed flip
      state[input_nodes] <- proposed_state[input_nodes]
    }

    # ------------------------------------------------
    # 2) Deterministic update for subsequent layers
    # ------------------------------------------------
    for (layer_idx in 2:length(layers)) {
      layer <- layers[[layer_idx]]
      for (node in layer) {
        # Summation of parent's influences + bias
        net_in <- biases_T[[node]]
        parents <- parent_map[[node]]
        for (parent in parents) {
          edge_key <- paste(parent, node, sep = "->")
          net_in   <- net_in + edge_map[[edge_key]] * state[[parent]]
        }
        # Threshold at 0 => +1 or -1
        if (net_in >= 0) {
          state[[node]] <- 1
        } else {
          state[[node]] <- -1
        }
      }
    }

    # Record the new state
    states[iter + 1, ] <- sapply(nodes, function(n) state[[n]])
  }

  return(list(states = states))
}

# ===============================================================
# layer_gibbs_sampler():
#   Implements a layer-wise Gibbs sampling approach.
#   - Each input node is sampled from a local posterior ~ exp(-loss)
#   - Hidden/output nodes updated deterministically
# ===============================================================
layer_gibbs_sampler <- function(
  iterations, nodes, layers, edges, biases, initial_state = NULL, temperature = 1
) {
  # Identify input nodes
  input_nodes <- layers[[1]]

  # Scale biases by temperature
  biases_T <- list()
  for (node in nodes) {
    biases_T[[node]] <- biases[[node]] / temperature
  }

  # Scale weights by temperature
  edges_T <- lapply(edges, function(e) list(
    from   = e$from,
    to     = e$to,
    weight = e$weight / temperature
  ))

  # Initialize the chain
  if (is.null(initial_state)) {
    # By default, random assignment
    state <- setNames(sample(c(-1, 1), length(nodes), replace = TRUE), nodes)
  } else {
    state <- initial_state
  }
  if (!is.list(state)) {
    state <- as.list(state)
  }

  # Set up a data.frame to record sampled states
  states <- data.frame(matrix(ncol = length(nodes), nrow = iterations + 1))
  colnames(states) <- nodes

  # Start with the initial state
  states[1, ] <- sapply(nodes, function(n) state[[n]])

  # Build parent & child maps
  parent_map <- list()
  child_map  <- list()
  for (node in nodes) {
    parent_map[[node]] <- c()
    child_map[[node]]  <- c()
  }
  for (e in edges_T) {
    parent_map[[e$to]] <- c(parent_map[[e$to]], e$from)
    child_map[[e$from]]<- c(child_map[[e$from]], e$to)
  }

  # ===============================================================
  # MAIN SAMPLING LOOP (layer-wise updates)
  # ===============================================================
  for (iter in 1:iterations) {
    # For each layer, update the nodes in that layer
    for (layer_idx in 1:length(layers)) {
      layer <- layers[[layer_idx]]
      for (node in layer) {
        # If it's an input node, we do a mini Gibbs step
        if (node %in% input_nodes) {

          # Evaluate the loss if node = +1 vs. node = -1
          # We'll store them in 'losses' for each possible value
          losses <- c()
          for (val in c(1, -1)) {
            temp_state      <- state
            temp_state[[node]] <- val

            # Compute the "input node" negative log-likelihood
            net_in_node     <- biases_T[[node]]
            prob_node       <- sigmoid(net_in_node)
            loss_node       <- compute_loss_NLL(val, prob_node)

            total_loss      <- loss_node

            # Also incorporate each child's penalty
            for (child in child_map[[node]]) {
              net_input_child <- biases_T[[child]]
              # Sum up parent's influences
              for (parent in parent_map[[child]]) {
                edge <- Filter(function(e) e$from == parent && e$to == child, edges_T)[[1]]
                net_input_child <- net_input_child + edge$weight * temp_state[[parent]]
              }
              prob_child     <- sigmoid(net_input_child)
              # We scale by #child_map[[node]] or weight magnitude, depending on logic
              loss_child     <- compute_loss_NLL(state[[child]], prob_child) /
                length(child_map[[node]]) / abs(edge$weight)

              total_loss     <- total_loss + loss_child
            }

            losses <- c(losses, total_loss)
          }

          # Convert those two losses into probabilities
          probs <- exp(-losses)
          probs <- probs / sum(probs)

          # Sample the node's new value from {+1, -1}
          state[[node]] <- sample(c(1, -1), 1, prob = probs)

        } else {
          # If it's not an input node, do a deterministic update
          net_in <- biases_T[[node]]
          for (parent in parent_map[[node]]) {
            edge <- Filter(function(e) e$from == parent && e$to == node, edges_T)[[1]]
            net_in <- net_in + edge$weight * state[[parent]]
          }
          # Threshold at 0
          if (net_in >= 0) {
            state[[node]] <- 1
          } else {
            state[[node]] <- -1
          }
        }
      }
    }
    # Store the new overall state
    states[iter + 1, ] <- sapply(nodes, function(n) state[[n]])
  }

  return(list(states = states))
}A.3Learning (LFP)
compute_weight_updates() and compute_outputs()
##########################################################
# compute_weight_updates():
#   Applies LFP-style updates to the weights of a neural network
#   based on a series of sampled states (counterfactuals).
#
#   1) We run a forward pass w/ "input_values" to get a_Oc^AW.
#   2) For each sample from 'samples', we compute an outcome reward,
#      distribute it backward through each layer, and accumulate
#      incremental weight & bias updates.
#
# Arguments:
#   samples            : data.frame of counterfactual states (rows).
#   edges              : list() of edges, each w/ (from, to, weight).
#   nodes              : structure containing nodes$input, nodes$hidden, nodes$output, etc.
#   biases             : named list of neuron biases (ex: biases[["N2"]]).
#   learning_rate      : scalar "eta" used in the final update step.
#   weight_update_rule : "Additive" or "Multiplicative" for applying updates.
#   input_values       : the 'real world' input, used for the forward pass to get a_Oc^AW.
#
# Returns a list with:
#   $weight_updates  : named list of net weight increments (or exponents),
#   $bias_updates    : named list of net bias increments (or exponents).
#
##########################################################
compute_weight_updates <- function(
  samples, edges, nodes, biases,
  learning_rate = 0.1,
  weight_update_rule = 'Additive',
  input_values
) {
  ############################################################
  # 1) Determine the actual outcome activation a_Oc_AW
  #    by running a forward pass with the real-world input_values.
  ############################################################
  {
    # We'll store activations_aw as a list of node->activation
    activations_aw <- list()

    # Set input activations from 'input_values'
    for (node in nodes$input) {
      activations_aw[[node]] <- input_values[[node]]
    }

    # We'll apply tanh() to hidden+output sequentially
    activation_function <- function(x) tanh(x)
    all_nodes_aw <- c(nodes$hidden, nodes$output)
    net_inputs_aw <- list()

    for (node in all_nodes_aw) {
      # gather incoming edges
      incoming_edges <- Filter(function(e) e$to == node, edges)
      net_in <- biases[[node]]
      for (e in incoming_edges) {
        from_node <- e$from
        w <- e$weight
        a_from <- activations_aw[[from_node]]
        net_in <- net_in + w * a_from
      }
      net_inputs_aw[[node]] <- net_in
      activations_aw[[node]] <- activation_function(net_in)
    }

    # We assume a single output node for the outcome
    output_node <- nodes$output[[1]]
    a_Oc_AW <- activations_aw[[output_node]]
  }

  ############################################################
  # 2) Initialize cumulative weight/bias updates
  ############################################################
  cumulative_weight_updates <- list()
  cumulative_bias_updates   <- list()
  for (edge in edges) {
    key <- paste(edge$from, edge$to, sep = "->")
    cumulative_weight_updates[[key]] <- 0
  }
  for (node in names(biases)) {
    cumulative_bias_updates[[node]] <- 0
  }

  num_samples <- nrow(samples)

  ############################################################
  # 3) For each sample in 'samples', do:
  #    - Forward pass => get net inputs & outputs
  #    - Compute a reward, r_{Oc}^i, as per eq. in the thesis
  #    - Backprop that reward using LFP logic
  #    - Accumulate the incremental delta weights
  ############################################################
  for (i in seq_len(num_samples)) {
    # Convert row i into a named list
    state_vector <- samples[i, ]
    state <- as.list(state_vector)
    names(state) <- colnames(samples)

    # Compute forward pass for this sample
    forward_result <- compute_outputs(state, edges, biases, nodes)
    outputs    <- forward_result$outputs
    net_inputs <- forward_result$net_inputs

    ########################################################
    # 3a) Compute the reward for the outcome node(s)
    #     eq: r_{Oc}^i = a_Oc^{AW} * a_Oc^i ( if a_Oc_AW > 0 )
    #         = abs(a_Oc^i)               ( if a_Oc_AW < 0 )
    ########################################################
    rewards <- list()
    output_nodes <- nodes$output
    for (out_node in output_nodes) {
      current_outcome_activation <- outputs[[out_node]]

      # If the real outcome is positive, reward is a_Oc^{AW} * a_Oc^i
      # If negative, we use abs(a_Oc^i) => flipping sign
      if (a_Oc_AW > 0) {
        r_out <- a_Oc_AW * current_outcome_activation
      } else {
        r_out <- abs(current_outcome_activation)
      }
      rewards[[out_node]] <- r_out
    }

    ############################################################
    # 3b) Backward pass of reward via LFP
    #     We process layers from output back to hidden, skipping input layer.
    ############################################################
    layers_rev <- rev(nodes$layers)

    for (layer in layers_rev) {
      # skip if it's the input layer
      if (all(layer %in% nodes$input)) {
        next
      }

      for (node_j in layer) {
        r_j <- rewards[[node_j]]
        if (is.null(r_j)) next

        # net input: z_j
        z_j <- net_inputs[[node_j]]
        z_j_sign <- sign(z_j)

        incoming_edges <- edges[sapply(edges, function(e) e$to == node_j)]
        z_j_pos <- 0
        z_j_neg <- 0
        z_ij_list <- list()

        # Decompose z_j into positive & negative contributions
        for (e in incoming_edges) {
          from_node <- e$from
          w_ij <- e$weight
          a_i  <- outputs[[from_node]]
          z_ij <- a_i * w_ij
          z_ij_list[[from_node]] <- z_ij

          if (z_ij >= 0) {
            z_j_pos <- z_j_pos + z_ij
          } else {
            z_j_neg <- z_j_neg + z_ij
          }
        }

        # Also incorporate bias in that decomposition
        z_ij_bias <- biases[[node_j]]
        z_ij_list[["bias"]] <- z_ij_bias
        if (z_ij_bias >= 0) {
          z_j_pos <- z_j_pos + z_ij_bias
        } else {
          z_j_neg <- z_j_neg + z_ij_bias
        }

        z_j_pos_abs <- abs(z_j_pos)
        z_j_neg_abs <- abs(z_j_neg)
        z_j_total_abs <- z_j_pos_abs + z_j_neg_abs + 1e-9  # small epsilon to avoid /0

        # Propagate reward backward
        for (e in incoming_edges) {
          from_node <- e$from
          w_ij <- e$weight
          a_i  <- outputs[[from_node]]
          z_ij <- z_ij_list[[from_node]]

          # fraction1 & fraction2 separate pos vs. neg side
          if (z_ij >= 0) {
            fraction1 <- z_j_pos_abs / z_j_total_abs
            fraction2 <- z_ij / (z_j_pos + 1e-9)
          } else {
            fraction1 <- z_j_neg_abs / z_j_total_abs
            fraction2 <- z_ij / (z_j_neg + 1e-9)
          }

          # r_ij = fraction1 * fraction2 * sign(z_j) * r_j
          r_ij <- fraction1 * fraction2 * z_j_sign * r_j

          # Add partial reward to the from_node
          if (is.null(rewards[[from_node]])) {
            rewards[[from_node]] <- r_ij
          } else {
            rewards[[from_node]] <- rewards[[from_node]] + r_ij
          }

          # Weight update eq:
          # delta_w_ij = (|w_ij| * a_i / z_j_total_abs) * sign(z_j) * r_j
          delta_w_ij <- (abs(w_ij) * a_i) / z_j_total_abs * z_j_sign * r_j
          delta_w_ij <- learning_rate * delta_w_ij

          key <- paste(from_node, node_j, sep="->")
          if (weight_update_rule == 'Additive') {
            cumulative_weight_updates[[key]] <- cumulative_weight_updates[[key]] + delta_w_ij
          } else if (weight_update_rule == 'Multiplicative') {
            cumulative_weight_updates[[key]] <- cumulative_weight_updates[[key]] * exp(delta_w_ij)
          } else {
            stop("Invalid weight_update_rule. Use 'Additive' or 'Multiplicative'.")
          }
        }

        # Bias update (treated as from a 'bias node' with a=1)
        delta_b_j <- (abs(biases[[node_j]]) * 1) / z_j_total_abs * z_j_sign * r_j
        delta_b_j  <- learning_rate * delta_b_j

        if (weight_update_rule == 'Additive') {
          cumulative_bias_updates[[node_j]] <- cumulative_bias_updates[[node_j]] + delta_b_j
        } else if (weight_update_rule == 'Multiplicative') {
          cumulative_bias_updates[[node_j]] <- cumulative_bias_updates[[node_j]] * exp(delta_b_j)
        } else {
          stop("Invalid weight_update_rule. Use 'Additive' or 'Multiplicative'.")
        }
      } # end for node_j
    } # end for layer
  } # end for i in samples

  # Return the net updates
  list(
    weight_updates = cumulative_weight_updates,
    bias_updates   = cumulative_bias_updates
  )
}


##########################################################
# tanh activation_function
##########################################################
activation_function <- function(x) {
  tanh(x)
}

##########################################################
# compute_outputs():
#   Given a partial 'state' for input nodes and an entire net of edges/biases,
#   do a forward pass across each layer, returning net inputs & outputs.
##########################################################
compute_outputs <- function(state, edges, biases, nodes) {
  net_inputs <- list()
  outputs    <- state  # initialize with the known input states

  layers <- nodes$layers
  for (layer in layers) {
    for (node in layer) {
      # If it's an input node, skip (already set)
      if (node %in% nodes$input) {
        next
      }
      # sum up w_ij*a_i + bias
      incoming_edges <- Filter(function(edge) edge$to == node, edges)
      net_in <- biases[[node]]
      for (e in incoming_edges) {
        from_node <- e$from
        weight    <- e$weight
        act_from  <- outputs[[from_node]]
        net_in    <- net_in + weight * act_from
      }

      net_inputs[[node]] <- net_in
      # e.g. tanh
      outputs[[node]] <- activation_function(net_in)
    }
  }
  list(net_inputs = net_inputs, outputs = outputs)
}A.4Relevance, importance and the full simulation
compute_lrp_importance(), compute_causal_impact_scores() and run_simulation()
# =====================================================================
# compute_lrp_importance():
#   Applies a Layer-Wise Relevance Propagation approach to a given
#   neural network state (weights, biases, final updated edges).
#
#   1) We do a forward pass with the actual-world input_values
#      to get a_Oc^AW (the outcome node's activation).
#   2) We do a second forward pass but store net_inputs for
#      each layer to guide the backward pass.
#   3) We initialize the outcome node with R=1,
#      then propagate relevance backward via an alpha-beta rule
#      (Equation or logic from your LRP chapter).
#
#   The final result is a named list R[...] of
#   "importance" or "relevance" assigned to each input node
#   (and hidden nodes, though typically we focus on input).
# =====================================================================
compute_lrp_importance <- function(
  input_values,
  weights,
  biases,
  nodes,
  edges,
  lrp_variant = 'alpha_beta',
  alpha = 1,
  beta = 0
) {
  ############################################################
  # 1) Forward pass to find a_Oc^AW for reference
  ############################################################
  {
    # For the real-world scenario
    activations_aw <- list()
    for (node in nodes$input) {
      activations_aw[[node]] <- input_values[[node]]
    }
    activation_function <- function(x) tanh(x)
    all_nodes_aw <- c(nodes$hidden, nodes$output)
    net_inputs_aw <- list()

    for (node in all_nodes_aw) {
      incoming_edges_aw <- Filter(function(e) e$to == node, edges)
      net_input_aw <- biases[[node]]
      for (e in incoming_edges_aw) {
        from_node <- e$from
        w <- weights[[paste(from_node, node, sep="->")]]
        a_from <- activations_aw[[from_node]]
        net_input_aw <- net_input_aw + w * a_from
      }
      net_inputs_aw[[node]] <- net_input_aw
      activations_aw[[node]] <- activation_function(net_input_aw)
    }
    # outcome node
    output_node <- nodes$output[[1]]
    a_Oc_AW <- activations_aw[[output_node]]
  }

  ############################################################
  # 2) Possibly adjust alpha,beta if outcome is negative
  #    (Equation or logic from alpha-beta LRP).
  ############################################################
  epsilon <- 1e-6
  if (a_Oc_AW > 0) {
    alpha <- 1 + epsilon
    beta  <- 0 + epsilon
  } else {
    alpha <- 0 + epsilon
    beta  <- -1 + epsilon
  }

  ############################################################
  # 3) Full forward pass for the LRP process itself
  ############################################################
  activations <- list()
  net_inputs  <- list()
  for (node in nodes$input) {
    activations[[node]] <- input_values[[node]]
  }

  activation_function <- function(x) tanh(x)
  all_nodes <- c(nodes$hidden, nodes$output)

  for (node in all_nodes) {
    incoming_edges_node <- Filter(function(e) e$to == node, edges)
    net_in <- biases[[node]]
    for (e in incoming_edges_node) {
      from_node <- e$from
      w <- weights[[paste(from_node, node, sep="->")]]
      a_from <- activations[[from_node]]
      net_in <- net_in + w * a_from
    }
    net_inputs[[node]] <- net_in
    activations[[node]] <- activation_function(net_in)
  }

  ############################################################
  # 4) Initialize relevance at the outcome node
  #    We set R[outcome_node] = 1
  ############################################################
  R <- list()
  output_node <- nodes$output[[1]]
  R[[output_node]] <- 1

  ############################################################
  # 5) Backward pass: alpha-beta LRP or other variants
  ############################################################
  all_nodes_rev <- rev(all_nodes)
  for (node in all_nodes_rev) {
    relevance <- R[[node]]
    if (is.null(relevance)) next

    incoming_edges_node <- Filter(function(e) e$to == node, edges)
    if (length(incoming_edges_node) == 0) {
      next  # skip input nodes
    }

    # gather activations + weights
    a_i <- sapply(incoming_edges_node, function(e) activations[[e$from]])
    w_ij <- sapply(incoming_edges_node, function(e) {
      weights[[paste(e$from, e$to, sep="->")]]
    })
    z_ij <- a_i * w_ij

    # handle alpha-beta or other variants
    if (lrp_variant == 'alpha_beta') {
      z_ij_pos <- pmax(0, z_ij)
      z_ij_neg <- pmin(0, z_ij)
      denom_pos <- sum(z_ij_pos) + 1e-9
      denom_neg <- sum(z_ij_neg) - 1e-9

      relevance_pos <- alpha * (z_ij_pos / denom_pos) * relevance
      relevance_neg <- beta  * (z_ij_neg / denom_neg) * relevance
      relevance_i   <- relevance_pos - relevance_neg
    } else if (lrp_variant == 'basic') {
      denominator  <- sum(z_ij) + 1e-9
      relevance_i  <- (z_ij / denominator) * relevance
    } else if (lrp_variant == 'softmax') {
      z_ij_exp    <- exp(z_ij / 1.0)
      denom       <- sum(z_ij_exp) + 1e-9
      relevance_i <- (z_ij_exp / denom) * relevance
    } else {
      stop("Invalid LRP variant. Choose 'alpha_beta', 'basic', or 'softmax'.")
    }

    # Normalize so sum(relevance_i) = relevance
    sum_rel_i <- sum(relevance_i)
    if (sum_rel_i > 1e-9) {
      relevance_i <- relevance_i / sum_rel_i * relevance
    }

    # Assign to each predecessor
    for (idx in seq_along(incoming_edges_node)) {
      from_node <- incoming_edges_node[[idx]]$from
      if (is.null(R[[from_node]])) {
        R[[from_node]] <- 0
      }
      R[[from_node]] <- R[[from_node]] + relevance_i[idx]
    }
  }

  # Return final relevance distribution
  return(R)
}


# =====================================================================
# compute_causal_impact_scores():
#   Uses the final importance_scores from LRP + the updated network
#   to compute kappa(C,O) for each cause set C.
#
#   (1) Identify # of edge-disjoint positive paths from C->O, if outcome>0
#       or a penalty if outcome<0.
#   (2) Identify idle causes in C that never appear on a positive path.
#   (3) Combine with sum(importance_scores[C]) in a ratio.
# =====================================================================
compute_causal_impact_scores <- function(
  importance_scores,
  network,
  input_values,
  outcome_node = NULL,
  cause_sets   = NULL,
  w            = 1,
  negation_handling = TRUE
) {
  ############################################################
  # PART 1: Setup & default cause_sets
  ############################################################
  if (is.null(outcome_node)) {
    outcome_node <- network$nodes$output[[1]]
  }
  if (is.null(cause_sets)) {
    # generate combos of up to size 3 from the input nodes
    input_nodes <- network$nodes$input
    cause_sets  <- list()
    for (size in 1:3) {
      if (size <= length(input_nodes)) {
        combos <- combn(input_nodes, size, simplify=FALSE)
        cause_sets <- c(cause_sets, combos)
      }
    }
  }

  ############################################################
  # PART 2: Forward pass to see outcome in the real world
  ############################################################
  activation_function <- function(x) tanh(x)
  activations <- list()
  for (node in network$nodes$input) {
    activations[[node]] <- input_values[[node]]
  }

  edges  <- network$edges
  biases <- network$biases
  all_nodes <- c(network$nodes$hidden, network$nodes$output)
  net_inputs <- list()

  for (nd in all_nodes) {
    incoming_e <- Filter(function(e) e$to == nd, edges)
    net_in     <- biases[[nd]]
    for (e in incoming_e) {
      from_node <- e$from
      w_ij      <- e$weight
      a_from    <- activations[[from_node]]
      net_in    <- net_in + w_ij*a_from
    }
    net_inputs[[nd]]    <- net_in
    activations[[nd]]   <- activation_function(net_in)
  }
  # real outcome
  a_O_AW <- activations[[outcome_node]]

  ############################################################
  # PART 3: Helpers for positive path logic
  ############################################################
  # We'll define is_hidden_contributing(), is_hidden_supported()
  # then count_edge_disjoint_paths() & count_idle_causes().

  is_hidden_contributing <- function(h) {
    # does h->outcome have w*h>0?
    e_hO <- Filter(function(e) e$from==h && e$to==outcome_node, edges)
    if (length(e_hO)!=1) return(FALSE)
    w_hO <- e_hO[[1]]$weight
    a_h  <- activations[[h]]
    return(w_hO*a_h>0)
  }

  is_hidden_supported <- function(h, C) {
    # does h get a positive push from any c in C?
    inedges_h <- Filter(function(e) e$to==h, edges)
    for (ed in inedges_h) {
      c_node <- ed$from
      if (c_node %in% C) {
        w_ch <- ed$weight
        a_c  <- activations[[c_node]]
        if (w_ch*a_c>0) {
          return(TRUE)
        }
      }
    }
    return(FALSE)
  }

  count_edge_disjoint_paths <- function(C) {
    # # of hidden neurons that are "positively activated" & supported by c in C
    path_count <- 0
    for (h in network$nodes$hidden) {
      if (is_hidden_contributing(h) && is_hidden_supported(h,C)) {
        path_count <- path_count+1
      }
    }
    path_count
  }

  count_idle_causes <- function(C) {
    # c is idle if it doesn't appear on any positive path
    idle_ct <- 0
    for (c in C) {
      used_by_any_hidden <- FALSE
      for (h in network$nodes$hidden) {
        if (!is_hidden_contributing(h)) next
        # is h supported by c?
        w_edge <- Filter(function(e) e$from==c && e$to==h, edges)
        if (length(w_edge)==1) {
          w_ch <- w_edge[[1]]$weight
          a_c  <- activations[[c]]
          if (w_ch*a_c>0) {
            used_by_any_hidden<-TRUE
            break
          }
        }
      }
      if (!used_by_any_hidden) {
        idle_ct <- idle_ct+1
      }
    }
    idle_ct
  }

  ############################################################
  # PART 3bis: NEGATIVE outcome logic (approx penalty)
  ############################################################
  # If outcome < 0, we do a simpler approach:
  #   Z=1 + penalty_count, where penalty_count
  #   lumps together all "oppositely-coded" or "fitting negative" cases.

  get_outgoing_weights <- function(c) {
    out_e <- Filter(function(e) e$from==c, edges)
    sapply(out_e, function(x) x$weight)
  }
  all_positive <- function(ws) { length(ws)>0 && all(ws>0) }
  all_negative <- function(ws) { length(ws)>0 && all(ws<0) }

  compute_penalty_for_cause <- function(c, a_c, positive_outcome) {
    w_list <- get_outgoing_weights(c)
    if (length(w_list)==0) return(0)

    if (positive_outcome) {
      # if c=+1 but all weights<0 => penalty
      # if c=-1 but all weights>0 => penalty
      if (a_c==1) {
        if (all_negative(w_list)) return(1) else return(0)
      } else {
        if (all_positive(w_list)) return(1) else return(0)
      }
    } else {
      # negative outcome => opposite pattern
      if (a_c==1) {
        if (all_positive(w_list)) return(1) else return(0)
      } else {
        if (all_negative(w_list)) return(1) else return(0)
      }
    }
  }

  compute_penalty_count <- function(C) {
    penalty_ct <- 0
    positive_outcome <- (a_O_AW>0)
    for (c in C) {
      a_c_init <- input_values[[c]]
      penalty_ct <- penalty_ct + compute_penalty_for_cause(c, a_c_init, positive_outcome)
    }
    penalty_ct
  }

  ############################################################
  # PART 4: Loop over cause_sets, compute sum_Rc, then define
  #         Z = #_ED + idle or 1 + penalty, then kappa= sum_Rc / (Z*w)
  ############################################################
  results <- data.frame(C=I(character(0)),
                        Z=numeric(0),
                        sum_Rc=numeric(0),
                        kappa=numeric(0),
                        stringsAsFactors=FALSE)

  for (C in cause_sets) {
    sum_Rc <- sum(unlist(importance_scores[C]), na.rm=TRUE)
    idle_count <- count_idle_causes(C)

    if (a_O_AW>0) {
      num_paths <- count_edge_disjoint_paths(C)
      Z_val     <- num_paths + idle_count
    } else {
      penalty_count <- compute_penalty_count(C)
      Z_val         <- 1 + penalty_count
    }

    kappa_val <- 0
    if (Z_val>0) {
      kappa_val <- sum_Rc/(Z_val*w)
    }

    results <- rbind(results, data.frame(
      C=paste(C, collapse="+"),
      Z=Z_val,
      sum_Rc=sum_Rc,
      kappa=kappa_val,
      stringsAsFactors=FALSE
    ))
  }

  results
}


# =====================================================================
# perform_sampling():
#   A small helper to unify the call for 'MH' vs. 'Gibbs'
#   samplers, returning the sample matrix + last state.
# =====================================================================
perform_sampling <- function(
  nodes, layers, edges, biases,
  initial_state, n_samples, sampling_method='MH'
) {
  if (sampling_method=='MH') {
    result <- mh_layered_sampler(
      iterations   = n_samples,
      nodes        = nodes,
      layers       = layers,
      edges        = edges,
      biases       = biases,
      initial_state= initial_state,
      temperature  = 1
    )
    samples_df <- result$states
  } else if (sampling_method=='Gibbs') {
    result <- layer_gibbs_sampler(
      iterations   = n_samples,
      nodes        = nodes,
      layers       = layers,
      edges        = edges,
      biases       = biases,
      initial_state= initial_state
    )
    samples_df <- result$states
  } else {
    stop("Unsupported sampling method: ", sampling_method)
  }

  # last row => last sample
  last_sample <- samples_df[nrow(samples_df),]
  last_sample_list <- as.list(last_sample)
  names(last_sample_list) <- names(last_sample)

  list(
    samples    = samples_df,
    last_sample= last_sample_list
  )
}


# =====================================================================
# run_simulation():
#   A "master" function that orchestrates:
#    1) repeated sampling of states,
#    2) LFP-style weight updates (either 'AsWeGo' or 'Cumulative'),
#    3) final LRP to get importance_scores,
#    4) computing causal impact scores,
#    5) returning the updated network, plus optional all-samples.
# =====================================================================
run_simulation <- function(
  network, initial_state, input_values,
  num_simulations       = 100,
  n_samples             = 20,
  sampling_method       = 'MH',
  weight_update_timing  = 'Cumulative',
  learning_rate         = 1,
  weight_update_rule    = "Additive",
  lrp_variant           = 'alpha_beta',
  alpha                 = 1,
  beta                  = 0,
  return_samples        = FALSE,
  cause_sets            = NULL,
  negation_handling     = TRUE,
  w                     = 1
) {
  # cat("Starting run_simulation...\n")

  original_network <- network

  # Extract node lists
  nodes <- list(
    input  = network$network$input_neurons,
    hidden = network$network$hidden_neurons,
    output = network$network$output_neurons,
    layers = network$layers
  )


  edges_list  <- original_network$edges
  biases_list <- original_network$biases

  # Initialize accumulators for 'Cumulative' approach
  total_weight_updates <- list()
  total_bias_updates   <- list()
  for (edge in edges_list) {
    key <- paste(edge$from, edge$to, sep="->")
    total_weight_updates[[key]] <- 0
  }
  for (nd in names(biases_list)) {
    total_bias_updates[[nd]] <- 0
  }

  final_networks <- list()
  if (return_samples) {
    all_samples <- list()
  }


  for (sim in seq_len(num_simulations)) {

      ##Commented out: can be added back if one wants to make the process verbose.

    # if (sim%%50==0) {
    #   cat("\nSimulation", sim, "of", num_simulations, "\n")
    # }

    # Start from original each time
    network <- original_network
    edges   <- network$edges
    biases  <- network$biases

    # We'll handle 'AsWeGo' or 'Cumulative' differently
    if (weight_update_timing=='AsWeGo') {
      # Weighted updates after each sample
      current_state <- initial_state
      for (sample_num in seq_len(n_samples)) {
        all_nodes <- unique(c(nodes$input, nodes$hidden, nodes$output))

        sampling_result <- perform_sampling(
          nodes         = all_nodes,
          layers        = nodes$layers,
          edges         = edges,
          biases        = biases,
          initial_state = current_state,
          n_samples     = 1,
          sampling_method = sampling_method
        )
        new_sample <- sampling_result$last_sample
        current_state <- new_sample

        if (return_samples) {
          all_samples[[length(all_samples)+1]] <- current_state
        }

        # LFP weight updates
        updates <- compute_weight_updates(
          samples            = sampling_result$samples,
          edges              = edges,
          nodes              = nodes,
          biases             = biases,
          learning_rate      = learning_rate,
          weight_update_rule = weight_update_rule,
          input_values       = input_values
        )

        # Apply these increments
        cumulative_weight_updates <- updates$weight_updates
        cumulative_bias_updates   <- updates$bias_updates

        for (edge_idx in seq_along(edges)) {
          key   <- paste(edges[[edge_idx]]$from, edges[[edge_idx]]$to, sep="->")
          d_w   <- cumulative_weight_updates[[key]]
          if (is.null(d_w)) d_w<-0
          if (weight_update_rule=='Additive') {
            edges[[edge_idx]]$weight <- edges[[edge_idx]]$weight + d_w
          } else {
            edges[[edge_idx]]$weight <- edges[[edge_idx]]$weight * exp(d_w)
          }
        }
        for (nd in names(biases)) {
          d_b <- cumulative_bias_updates[[nd]]
          if (is.null(d_b)) d_b<-0
          if (weight_update_rule=='Additive') {
            biases[[nd]] <- biases[[nd]]+d_b
          } else {
            biases[[nd]] <- biases[[nd]]*exp(d_b)
          }
        }
      } # end sample_num

      final_networks[[sim]] <- list(edges=edges,biases=biases)

    } else if (weight_update_timing=='Cumulative') {
      # We gather all updates first, then apply once
      current_state <- initial_state
      for (sample_num in seq_len(n_samples)) {
        all_nodes <- unique(c(nodes$input, nodes$hidden, nodes$output))

        sampling_result <- perform_sampling(
          nodes         = all_nodes,
          layers        = nodes$layers,
          edges         = edges,
          biases        = biases,
          initial_state = current_state,
          n_samples     = 1,
          sampling_method = sampling_method
        )
        new_sample <- sampling_result$last_sample
        current_state <- new_sample

        if (return_samples) {
          all_samples[[length(all_samples)+1]] <- current_state
        }

        updates <- compute_weight_updates(
          samples            = sampling_result$samples,
          edges              = edges,
          nodes              = nodes,
          biases             = biases,
          learning_rate      = learning_rate,
          weight_update_rule = weight_update_rule,
          input_values       = input_values
        )

        c_w_updates <- updates$weight_updates
        c_b_updates <- updates$bias_updates

        for (key in names(c_w_updates)) {
          dw <- c_w_updates[[key]]
          if (is.null(dw)) dw<-0
          total_weight_updates[[key]]<- total_weight_updates[[key]]+dw
        }
        for (nd in names(c_b_updates)) {
          db <- c_b_updates[[nd]]
          if (is.null(db)) db<-0
          total_bias_updates[[nd]] <- total_bias_updates[[nd]]+db
        }
      } # end sample_num
    } else {
      stop("Invalid weight_update_timing. Use 'AsWeGo' or 'Cumulative'.")
    }
  } # end for sim

  # After all simulations, finalize
  if (weight_update_timing=='AsWeGo') {

    # We average the final networks over num_simulations
    averaged_edges  <- original_network$edges
    averaged_biases <- original_network$biases

    weight_sums <- list()
    bias_sums   <- list()
    for (ed in averaged_edges) {
      k <- paste(ed$from, ed$to, sep="->")
      weight_sums[[k]] <- 0
    }
    for (nd in names(averaged_biases)) {
      bias_sums[[nd]] <- 0
    }

    for (sim in seq_len(num_simulations)) {
      sim_edges <- final_networks[[sim]]$edges
      sim_biases<- final_networks[[sim]]$biases
      for (ed in sim_edges) {
        k <- paste(ed$from, ed$to, sep="->")
        weight_sums[[k]]<- weight_sums[[k]]+ed$weight
      }
      for (nd in names(sim_biases)) {
        bias_sums[[nd]]<- bias_sums[[nd]]+sim_biases[[nd]]
      }
    }
    for (ed_idx in seq_along(averaged_edges)) {
      k <- paste(averaged_edges[[ed_idx]]$from, averaged_edges[[ed_idx]]$to, sep="->")
      av_w  <- weight_sums[[k]]/num_simulations
      averaged_edges[[ed_idx]]$weight <- av_w
    }
    for (nd in names(averaged_biases)) {
      averaged_biases[[nd]]<- bias_sums[[nd]]/num_simulations
    }

    averaged_weights<-list()
    for (ed in averaged_edges) {
      k<- paste(ed$from, ed$to, sep="->")
      averaged_weights[[k]]<- ed$weight
    }

    # compute LRP-based importance on the final averaged network
    importance_scores <- compute_lrp_importance(
      input_values = input_values,
      weights      = averaged_weights,
      biases       = averaged_biases,
      nodes        = nodes,
      edges        = averaged_edges,
      lrp_variant  = lrp_variant,
      alpha        = alpha,
      beta         = beta
    )
    updated_network <- list(
      nodes  = nodes,
      edges  = averaged_edges,
      biases = averaged_biases
    )

  } else {

    # average the total updates
    num_total_updates <- num_simulations*n_samples
    avg_w_updates <- list()
    for (k in names(total_weight_updates)) {
      avg_w_updates[[k]] <- total_weight_updates[[k]]/num_total_updates
    }
    avg_b_updates <- list()
    for (nd in names(total_bias_updates)) {
      avg_b_updates[[nd]] <- total_bias_updates[[nd]]/num_total_updates
    }

    edges <- original_network$edges
    biases<- original_network$biases
    for (ed_idx in seq_along(edges)) {
      k<- paste(edges[[ed_idx]]$from, edges[[ed_idx]]$to, sep="->")
      dw<- avg_w_updates[[k]]
      if (is.null(dw)) dw<-0
      if (weight_update_rule=='Additive') {
        edges[[ed_idx]]$weight<- edges[[ed_idx]]$weight+dw
      } else {
        edges[[ed_idx]]$weight<- edges[[ed_idx]]$weight*exp(dw)
      }
    }
    for (nd in names(biases)) {
      db<- avg_b_updates[[nd]]
      if (is.null(db)) db<-0
      if (weight_update_rule=='Additive') {
        biases[[nd]]<- biases[[nd]]+db
      } else {
        biases[[nd]]<- biases[[nd]]*exp(db)
      }
    }
    updated_weights<- list()
    for (ed in edges) {
      k<- paste(ed$from, ed$to, sep="->")
      updated_weights[[k]]<- ed$weight
    }

    importance_scores <- compute_lrp_importance(
      input_values = input_values,
      weights      = updated_weights,
      biases       = biases,
      nodes        = nodes,
      edges        = edges,
      lrp_variant  = lrp_variant,
      alpha        = alpha,
      beta         = beta
    )
    updated_network <- list(
      nodes  = nodes,
      edges  = edges,
      biases = biases
    )
  }

  if (return_samples) {
    all_samples_df <- do.call(rbind,
      lapply(all_samples, function(x) as.data.frame(t(unlist(x))))
    )
    rownames(all_samples_df)<-NULL
  }
  result_list <- list(
    updated_network    = updated_network,
    importance_scores  = importance_scores
  )
  if (return_samples) {
    result_list$all_samples <- all_samples_df
  }


  # 7) Once we have importance_scores + updated_network:

  impact_scores <- compute_causal_impact_scores(
    importance_scores  = result_list$importance_scores,
    network            = result_list$updated_network,
    input_values       = input_values,
    cause_sets         = cause_sets,
    w                  = w,
    negation_handling  = negation_handling
  )

  result_list$impact_scores <- impact_scores

  return(result_list)
}
B Sampling diagnostics
The states each sampler visits most, for the rule of Experiment 1 and for the dissertation’s Boys & Girls example, E \leftarrow J, B, D and E \leftarrow M, S, C (a party is a success if all the boys or all the girls come), where J is less likely to come (0.5) than everyone else (0.8). Each sampler ran 2,000 chains of 100 steps from the actual world in which everyone attends.
| Sampler | State | Share of samples | Mean stay (steps) |
|---|---|---|---|
| Metropolis–Hastings | ¬A ¬B C | 48.0% | 7.1 |
| ¬A B C | 44.5% | 6.7 | |
| A B C | 2.9% | 2.6 | |
| ¬A ¬B ¬C | 2.0% | 1.5 | |
| ¬A B ¬C | 1.4% | 1.5 | |
| Gibbs | ¬A ¬B C | 47.1% | 2.4 |
| ¬A B C | 44.8% | 2.4 | |
| ¬A B ¬C | 2.5% | 1.0 | |
| A B C | 1.9% | 1.1 | |
| ¬A ¬B ¬C | 1.9% | 1.0 |
| Sampler | State | Share of samples | Mean stay (steps) |
|---|---|---|---|
| Metropolis–Hastings | J B D M S C | 41.6% | 29.4 |
| ¬J B D M S C | 16.7% | 9.0 | |
| ¬J B ¬D M S C | 3.9% | 2.6 | |
| ¬J ¬B D M S C | 3.8% | 2.6 | |
| J ¬B D M S C | 3.7% | 4.2 | |
| Gibbs | ¬J B D M S C | 18.8% | 1.5 |
| J B D M S C | 13.4% | 1.7 | |
| ¬J B D M S ¬C | 5.3% | 1.2 | |
| ¬J B D M ¬S C | 5.1% | 1.2 | |
| J B ¬D M S C | 4.8% | 1.2 |
C Data
Ratings from Experiment 2 are loaded from models/_data/data-conj-disj.csv. Participants who failed either comprehension check (the number of white balls, and the winning rule) are excluded, and each trial is assigned to its round from the urn contents and the drawn balls. Ratings are kept on the experiment’s 1–9 scale. The ratings of Morris et al. (2019) used in Figure 4 are the two files reanalysed by Quillien and Lucas (2023), copied to models/_data/morris-2019/; the rest of their materials is available with the article.
exp2_ratings() and exp2_summary()
# Experiment 2 (plural causes, disjunctive rule): participant-level ratings.
# Same exclusions and scenario coding as the original notebook chunk; keeps
# individual responses so means come with 95% intervals.
# Ratings are on the experiment's 1-9 scale (response 0-8 + 1).

exp2_letters <- function(q) {
  if (is.na(q)) return(NA_character_)
  l <- unlist(regmatches(q, gregexpr("[A-D]", q)))
  if (!length(l)) return(NA_character_)
  paste(sort(unique(l)), collapse = ",")
}

exp2_ratings <- function(path = "_data/data-conj-disj.csv") {
  raw <- readr::read_csv(path, show_col_types = FALSE)
  fail1 <- raw$subject_ID[raw$trial_index == "17.WhiteBalls" & raw$response != "2"]
  fail2 <- raw$subject_ID[raw$trial_index == "17.WinningCondition" &
                           raw$response != "You must draw two yellow, or two purple balls"]
  d <- raw[!(raw$subject_ID %in% unique(c(fail1, fail2))), ]
  pick <- function(a, b, c, dd) {
    d$`urn-A-n-colored-balls` == 14 & d$`urn-A-is-results-color` == a &
    d$`urn-B-n-colored-balls` == 2  & d$`urn-B-is-results-color` == b &
    d$`urn-C-n-colored-balls` == 4  & d$`urn-C-is-results-color` == c &
    d$`urn-D-n-colored-balls` == 18 & d$`urn-D-is-results-color` == dd
  }
  d$scenario <- NA_character_
  d$scenario[pick(TRUE, TRUE, TRUE, TRUE)]     <- "overdetermined positive"
  d$scenario[pick(TRUE, TRUE, FALSE, TRUE)]    <- "triple 1"
  d$scenario[pick(FALSE, FALSE, FALSE, FALSE)] <- "overdetermined negative"
  d$scenario[pick(FALSE, FALSE, TRUE, FALSE)]  <- "triple 0"
  d <- d[!is.na(d$scenario), ]
  d$cause_set <- vapply(d$question, exp2_letters, character(1))
  d$rating <- suppressWarnings(as.numeric(d$response)) + 1
  d <- d[!is.na(d$cause_set) & !is.na(d$rating), c("subject_ID", "scenario", "cause_set", "rating")]
  d
}

exp2_summary <- function(d) {
  d |>
    dplyr::group_by(scenario, cause_set) |>
    dplyr::summarise(n = dplyr::n(), mean = mean(rating), sd = stats::sd(rating),
                     .groups = "drop") |>
    dplyr::mutate(se = sd / sqrt(n), lo = mean - stats::qt(.975, n - 1) * se,
                  hi = mean + stats::qt(.975, n - 1) * se)
}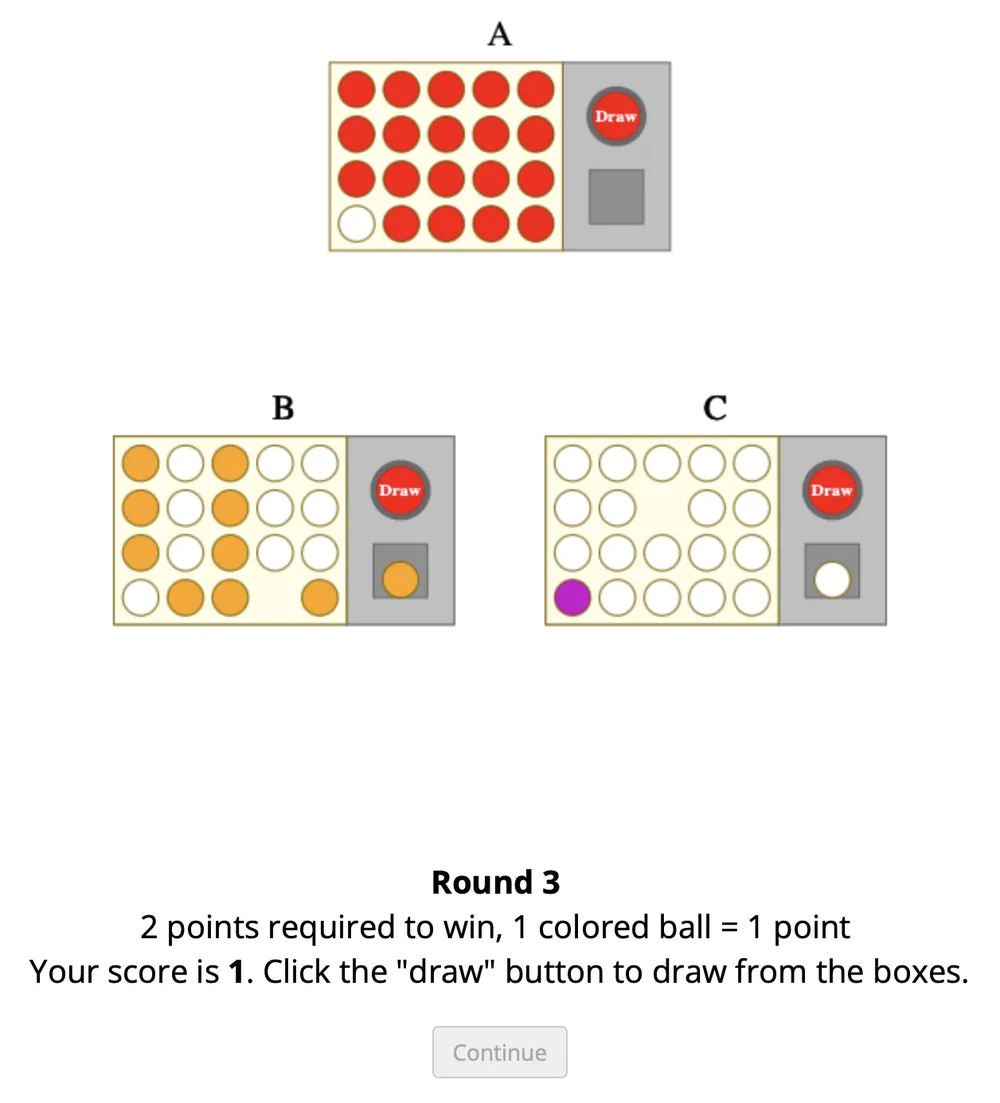
D Fitting
The grid search simulates the model once per learning rate and round, then applies every exponent \gamma to the same simulated importances, since \gamma only rescales them. Figure 8 shows the correlation over the grid for both variants.
With the AsWeGo timing (learning rate 0.2, as in the original notebook) the same minimal programs give Figure 9.
- P(A) = 0.1
- P(A) = 0.5
- P(A) = 0.9
- Other levels of P(A)
_R/compute/fit.R
# Fit to Experiment 2 (notebook Fig. 6, Table 4, Fig. 8).
# Raw kappa is simulated once per learning rate and scenario; gamma is applied
# afterwards (it only rescales). Grids as in the original notebook.
source("_R/compute/common.R")
source("_R/data_exp2.R")
seed <- 2029; set.seed(seed); started <- Sys.time()
ratings <- exp2_ratings()
means <- exp2_summary(ratings)
grids <- list(Cumulative = list(eta = seq(0.5, 1.5, 0.05), gamma = seq(0.4, 0.7, 0.02)),
              AsWeGo     = list(eta = seq(0.1, 0.25, 0.01), gamma = seq(0.5, 0.65, 0.02)))
published <- list(Cumulative = c(eta = 1.15, gamma = 0.58), AsWeGo = c(eta = 0.13, gamma = 0.56))
raw <- list()
for (tm in names(grids)) for (eta in unique(c(grids[[tm]]$eta, published[[tm]][["eta"]]))) for (sc in exp2_scenarios) {
  k <- raw_kappa(get_scenario_info(sc), 20, eta, tm)
  raw[[length(raw) + 1]] <- data.frame(timing = tm, eta = eta, scenario = sc, k)
  message(tm, " eta=", eta, " ", sc)
}
raw <- do.call(rbind, raw)
j <- merge(raw, means[, c("scenario", "cause_set", "mean")], by = c("scenario", "cause_set"))
search <- do.call(rbind, lapply(names(grids), function(tm) {
  do.call(rbind, lapply(unique(j$eta[j$timing == tm]), function(eta) {
    d <- j[j$timing == tm & abs(j$eta - eta) < 1e-9, ]
    do.call(rbind, lapply(grids[[tm]]$gamma, function(g) {
      data.frame(timing = tm, eta = eta, gamma = g, r = cor(pmax(d$kappa, 0)^g, d$mean))
    }))
  }))
}))
# Individual-level fit at the published parameters: lm(rating ~ 0 + prediction), K = 2
indiv <- lapply(names(published), function(tm) {
  p <- published[[tm]]
  d <- raw[raw$timing == tm & abs(raw$eta - p[["eta"]]) < 1e-9, ]
  d$pred <- pmax(d$kappa, 0)^p[["gamma"]]
  x <- merge(transform(ratings, scaled = (rating - 1) / 8), d[, c("scenario", "cause_set", "pred")],
             by = c("scenario", "cause_set"))
  fit <- lm(scaled ~ 0 + pred, data = x)
  ll <- as.numeric(logLik(fit)); n <- nrow(x); K <- 2
  data.frame(timing = tm, eta = p[["eta"]], gamma = p[["gamma"]], n_obs = n, logLik = ll,
             AIC = 2 * K - 2 * ll, BIC = log(n) * K - 2 * ll)
})
save_result(list(raw = raw, search = search, individual = do.call(rbind, indiv), published = published),
            "fit", seed, list(n_samples = 20, n_sims = 500, grids = grids), started)
E Reproduce
Every number on this page is computed from the code shown, except the predictions drawn in Figure 6, which are the dissertation’s published Cumulative predictions (models/_data/comparison_df_cumulative_extracted.csv); Table 4 recomputes them. The long computations run as scripts, each with a fixed seed, and save plain data to models/_results/ together with a record of how they were made (Table 7). The page reads those results; rendering it never reruns a simulation.
cd models
# several hours in all
bash _R/run-computations.sh sampling fit sensitivity inflation
# rebuilds both notebooks from the saved results and runs the site checks
cd .. && bash _tools/render.sh| Result | Seed | Run time (min) | Date (UTC) | R |
|---|---|---|---|---|
sampling | 2026 | 12.9 | 2026-10-10 | 4.3.3 |
fit | 2029 | 45.9 | 2026-10-10 | 4.3.3 |
sensitivity | 2028 | 25.4 | 2026-10-10 | 4.3.3 |
inflation | 2027 | 161.6 | 2026-10-10 | 4.3.3 |
_R/compute/sampling.R
# Counterfactual sampling diagnostics (notebook Fig. 3 and Appendix B).
# Experiment 1 rule and the dissertation's Boys & Girls example; MH and Gibbs;
# 2000 chains x 100 steps from the actual world. Saves visit counts, stays and
# transitions between input states (hidden units follow deterministically).
source("_R/compute/common.R")
seed <- 2026; set.seed(seed); started <- Sys.time()
n_chains <- as.integer(Sys.getenv("NB_CHAINS", "2000")); n_steps <- 100

cases <- list(
  exp1 = list(clauses = list(list(head = "E", body = c("A", "B")), list(head = "E", body = c("A", "C")),
                             list(head = "E", body = c("B", "C"))),
              priors = list(A = 0.05, B = 0.5, C = 0.95), world = list(A = 1, B = 1, C = 1, E = 1)),
  bg = list(clauses = list(list(head = "F", body = c("J", "B", "D")), list(head = "F", body = c("M", "S", "C"))),
            priors = list(J = 0.5, B = 0.8, D = 0.8, M = 0.8, S = 0.8, C = 0.8),
            world = list(J = 1, B = 1, D = 1, M = 1, S = 1, C = 1, F = 1))
)
out <- list()
for (cn in names(cases)) {
  cs <- cases[[cn]]
  net <- generate_network_from_logic_program(cs$clauses, cs$priors, plot_network = FALSE)
  init <- generate_initial_hidden_states(cs$world, net$network)
  inputs <- net$layers[[1]]
  for (sm in c("MH", "Gibbs")) {
    fn <- if (sm == "MH") mh_layered_sampler else layer_gibbs_sampler
    seqs <- vector("list", n_chains)
    for (k in seq_len(n_chains)) {
      st <- fn(iterations = n_steps, nodes = net$nodes, layers = net$layers, edges = net$edges,
               biases = net$biases, initial_state = init, temperature = 1)$states
      seqs[[k]] <- st[, inputs, drop = FALSE]
    }
    keys <- unlist(lapply(seqs, function(s) apply(s, 1, paste, collapse = ",")))
    visits <- as.data.frame(table(state = keys), stringsAsFactors = FALSE)
    tr <- build_transition_counts_and_stays(seqs, inputs)
    trans <- do.call(rbind, lapply(names(tr$transition_counts), function(from) {
      to <- tr$transition_counts[[from]]
      data.frame(from = from, to = names(to), count = unlist(to), stringsAsFactors = FALSE)
    }))
    stays <- data.frame(state = names(tr$stay_counts), mean_stay = sapply(tr$stay_counts, mean),
                        n_visits = sapply(tr$stay_counts, length), stringsAsFactors = FALSE)
    out[[cn]][[sm]] <- list(visits = visits, transitions = trans, stays = stays,
                            inputs = inputs, actual = paste(unlist(cs$world[inputs]), collapse = ","))
    message(cn, " ", sm, " done")
  }
  out[[cn]]$network <- list(edges = net$edges, biases = net$biases, layers = net$layers)
}
save_result(out, "sampling", seed, list(chains = n_chains, steps = n_steps), started)
_R/compute/sensitivity.R
# Sensitivity of kappa(A, E) to the number of samples n and learning rate eta
# (notebook Fig. 5). P(A) = 0.1, P(B) = 0.9; 10000 samples in total per point.
source("_R/compute/common.R")
seed <- 2028; set.seed(seed); started <- Sys.time()
grid <- expand.grid(n = c(10, 20, 50, 100, 200, 500), eta = c(0.1, 0.25, 0.5, 0.75, 1),
                    structure = c("conjunctive", "disjunctive"), timing = c("Cumulative", "AsWeGo"),
                    stringsAsFactors = FALSE)
grid$kappaA <- NA_real_
for (i in seq_len(nrow(grid))) {
  g <- grid[i, ]
  info <- list(clauses = build_minimal_program(g$structure), input_probabilities = list(A = 0.1, B = 0.9),
               initial_state = list(A = 1, B = 1, E = 1))
  k <- raw_kappa(info, g$n, g$eta, g$timing, num_simulations = 10000 / g$n)
  grid$kappaA[i] <- k$kappa[k$cause_set == "A"]
  if (i %% 10 == 0) message(i, "/", nrow(grid))
}
save_result(grid, "sensitivity", seed, list(pA = 0.1, pB = 0.9, total_samples = 10000), started)
_R/compute/inflation.R
# Abnormal inflation and deflation in the minimal programs (notebook Fig. 4).
# kappa(A, E) over a 9 x 9 grid of P(A), P(B); n = 50 samples, 500 chains;
# learning rate 1 (Cumulative) and 0.2 (AsWeGo), as in the original notebook.
source("_R/compute/common.R")
seed <- 2027; set.seed(seed); started <- Sys.time()
grid <- expand.grid(pA = seq(0.1, 0.9, 0.1), pB = seq(0.1, 0.9, 0.1),
                    structure = c("conjunctive", "disjunctive"), timing = c("Cumulative", "AsWeGo"),
                    stringsAsFactors = FALSE)
n_samples <- 50; n_sims <- as.integer(Sys.getenv("NB_SIMS", "500"))
grid$kappaA <- NA_real_
for (i in seq_len(nrow(grid))) {
  g <- grid[i, ]
  info <- list(clauses = build_minimal_program(g$structure), input_probabilities = list(A = g$pA, B = g$pB),
               initial_state = list(A = 1, B = 1, E = 1))
  lr <- if (g$timing == "AsWeGo") 0.2 else 1
  k <- raw_kappa(info, n_samples, lr, g$timing, num_simulations = n_sims)
  grid$kappaA[i] <- k$kappa[k$cause_set == "A"]
  if (i %% 20 == 0) message(i, "/", nrow(grid))
}
morris <- function(path, structure) {
  d <- read.csv(path)
  d <- d[d$rating > -1, ]
  d$rating <- d$rating + 1   # 1-9 scale
  d$pA <- d$green_prob / 10; d$pB <- d$blue_prob / 10
  d |> group_by(pA, pB) |> summarise(n = n(), mean = mean(rating), se = sd(rating) / sqrt(n()), .groups = "drop") |>
    mutate(structure = structure)
}
m <- "_data/morris-2019"   # from the OSF materials of Quillien & Lucas (2023), reanalysis of Morris et al. (2019)
people <- rbind(morris(file.path(m, "data_con.csv"), "conjunctive"), morris(file.path(m, "data_dis.csv"), "disjunctive"))
save_result(list(model = grid, people = people), "inflation", seed,
            list(n_samples = n_samples, n_sims = n_sims, lr = c(Cumulative = 1, AsWeGo = 0.2)), started)
© 2026 Can Konuk
Stanford, California